Get in touch
Open to principal-scope roles · Phoenix, Arizona · Remote or hybrid
Open to principal-scope roles · Phoenix, Arizona · Remote or hybrid
Learn AI · guided paths, a living map and two illustrated lessons
AI is a web of ideas, not a glossary. This page lays out the forty-four ideas that matter as neurons on a map, from what a model is to when an agent is the right call: touch one and it fires into the ideas it depends on. Every idea is written three ways, so a curious parent and a new product manager can read the same map and stop at different depths. Below the map: where each idea sits in the stack, what separates a chatbot from an agent, how an agent actually thinks, and the questions people ask me most.
Start here
New to this: six short guided paths, in order, each ending with something you can picture and explain. Designing a system: say what you are building and get the route. Or wander: the map, the lessons and the stack are all open, and your progress is kept either way.
Door 1
Six short paths, in order. Each one ends with something you can picture and explain.
Door 2
Say what you are building. Get the lesson to watch, the gate to run, the playbook and a worked example.
Door 3
The living map, the two atlas lessons, the stack, the questions people ask. Go anywhere; progress is kept.
The SHAMS AI Atlas
The map below teaches the words. The atlas puts them to work: one customer request followed through an illustrated, governed AI system, from who owns the goal to what the model proposes, what is checked before anything happens, and how the run ends. Switch between the picture and the architecture it stands for, turn on the SHAMS lenses, then break things on purpose: remove the evidence, deny a permission, make a tool fail, add a specialist.
Follow one request See a denied action Meet the specialist The architecture view How a model is made
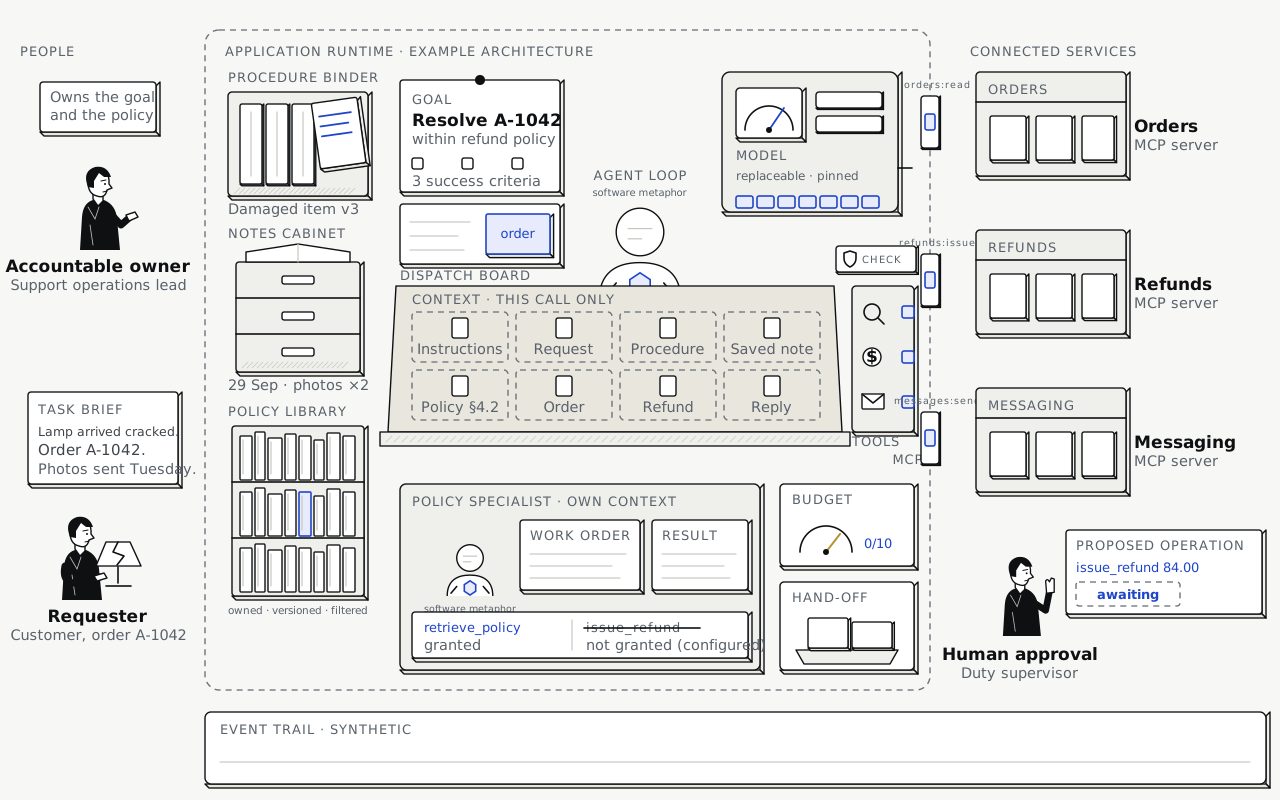
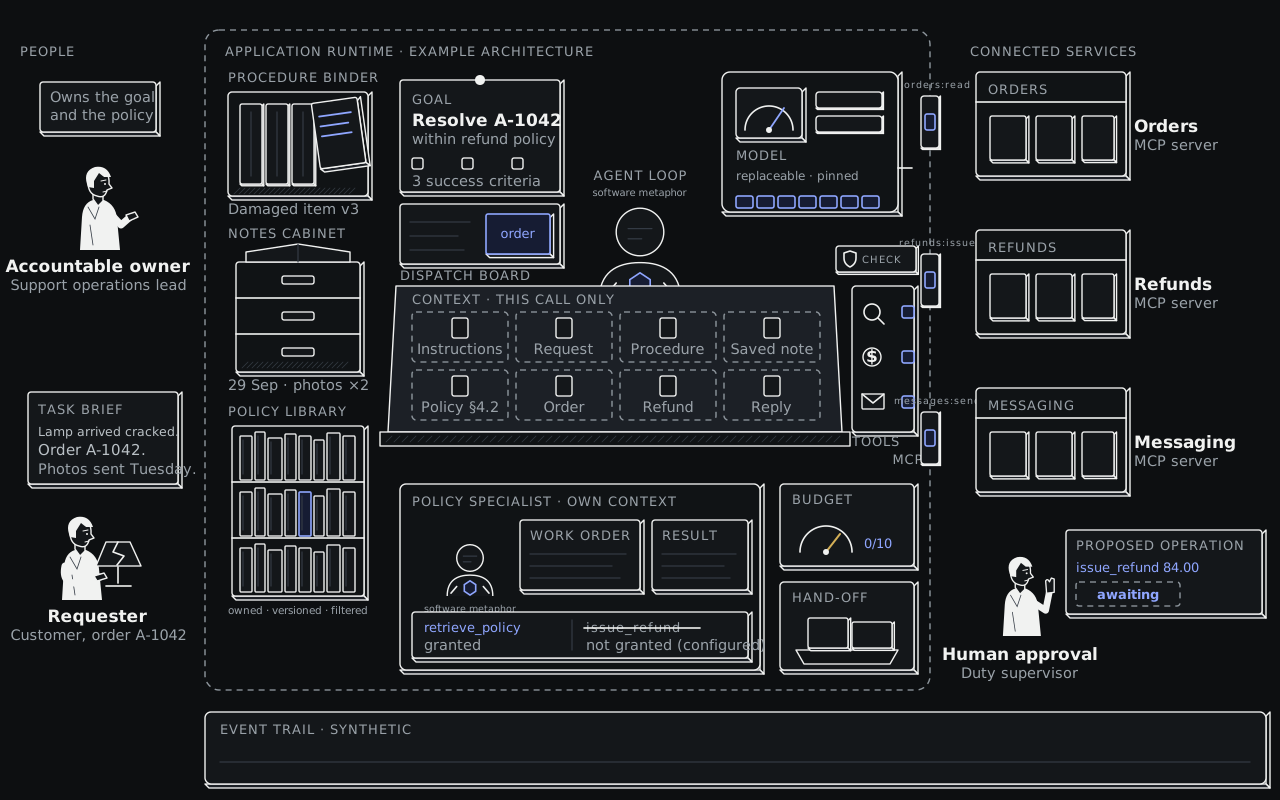
43 concepts across two lessons so far, each with a picture, three depths, its boundaries and where the analogy stops. Teaching simulation; all data synthetic.
The map
Left to right: the foundations, how machines learn, how language models work, what turns a model into an agent, what it takes to run one safely, and how to decide whether you should. Tap any idea, or zoom to a cluster. Mark it "I get this" and it lights up; when two ideas you understand are linked, the link between them glows. Pick a guided circuit if you'd rather be walked through.
Progress is saved in this browser only. Nothing is sent anywhere.
Nobody needs to understand a transformer to run a company on one. They need to know what it may do, where it gets its facts, and who can stop it.
The stack
Most confusion about AI comes from mixing layers: arguing about the model when the problem is the data, or buying an agent framework when what's missing is a guardrail. Read bottom to top. Each layer only works if the one under it is in place, and that order is also the order I build in.
Where AI meets the work: the assistant in a tool, the copilot in a workflow, the approval a person gives before anything irreversible happens.
The parts that make it safe to run: checks in code that the model cannot talk its way past, tests that run on every change, traces that explain what happened, and an off switch.
The loop that decides, acts, checks the result, and repeats until the job is done. One agent for a narrow job; a coordinator with specialists for a broad one.
How the model asks your software to do something. The model never runs anything itself; it emits a structured request, your code validates and executes it, and the result goes back as a message. MCP lives here, between the agent and your systems: it standardises how tools and data are plugged in, so each integration is built once and works with any model. It standardises the connection, not the permission. Who may call what is still yours to enforce.
Everything placed in front of the model for this one request: the standing instructions, what you typed, documents retrieved for the question, and memory brought back in. The model sees only this, nothing else.
The trained thing that predicts. Large language models write; embedding models turn meaning into numbers; small models classify and extract. Fine-tuning adjusts behaviour; it does not add facts reliably.
What the model learned from, and what your organisation owns: documents, databases, the lakehouse, the labels on the examples. Every fact the system states comes from here or from the model's training, and only one of those is governed by you.
How does the stack affect delivery? Explore the components, team design and coordination costs, with a free one-page field guide.
The same seven layers are the inner ring of the estate map in the SHAMS Method, and the build order in every playbook.
Four kinds
People say "AI" for all four. The difference is who decides the next step and who takes the action. That difference is also where the risk lives, which is why I ask it first in every engagement.
Most organisations should start at assistant or workflow and earn their way to agents. The autonomy ladder is how I decide when a system is ready to move right.
When to build an agent
An agent is the most expensive and least predictable of the four kinds, so it has to earn its place. Walk the questions in order. The first "yes" tells you what to build. Wherever you land, you can move one step to the right later, once the gates for that step are passed; that is the whole idea of the autonomy ladder.
Why this order
Each kind to the right costs more to build, more to run, and more when it is wrong. A workflow fails in one visible place; an agent fails somewhere in a loop nobody drew. So the question is never "could an agent do this?" (usually yes) but "what is the simplest kind that delivers the value?" Teams that start one step simpler ship in weeks, learn what the real steps are, and then have the evidence to move right.
Pick the simplest kind that delivers the value. Move right one rung at a time, and only through the gates.
The controls in the last question are gates 05 to 08 of the eight gates. The gate check tells you in a few minutes which ones you are missing.
How an agent thinks
Strip away the frameworks and every agent is this loop. Your code sends the model the conversation so far. The model replies and says why it stopped: either it wants a tool run, or it is finished. If it wants a tool, your code runs it, appends the result, and goes round again. The only honest exit is the model's own stop reason.
Ways people break the loop
Read the stop reason for each response. Validate every tool call. Count the run as a success only when the goal is verified; a turn, time or cost limit is a legitimate exit, reported as exactly that. See a budget exit.
More than one agent
When the job is too broad for one agent, don't give one agent more tools. Give a coordinator the goal, let it split the work among specialists that each hold a narrow set of tools, and have it assemble the results. Each specialist works in its own isolated context: it cannot see the others' work, which is exactly what keeps it focused and cheap.
The common mistake
The coordinator decomposes too narrowly. Asked why one tenant's requests are slow, it sends a specialist to check database CPU and nothing else, and the answer misses lock contention, a recent deployment and a noisy neighbour. I have watched people make the same mistake before any agent was involved: resize first, understand later. The fix is not a smarter coordinator. It is a goal ("find why this tenant is slow, with evidence") rather than a pre-baked task, and a result format that carries the evidence back.
Give goals, not task lists. Keep specialists narrow. Keep their context separate.
How many specialists is too many? Run the coordination cost: ten agents in a full mesh is 45 possible links, through a coordinator it is 9.
The enforcement question
Anything you write in a prompt is guidance the model usually follows. A rule you need to hold is a check in code that runs outside the model, at the boundary the action crosses, and decides allow, deny or ask a person. A hook is one place such a check can live, but not every hook enforces anything: some only log, and some ask another model. Name the behaviour you need and where it runs. And remember that code can be wrong too, so the check gets tests like anything else.
Prompt-based
Lives in the system prompt. The model reads it, weighs it against everything else in the context, and usually complies. Usually. Under pressure from a long conversation, a persuasive user, or an ambiguous case, it can be argued out of it, and you will not know until the refund has gone. Good for shaping how it works; not enough on its own for what it may do.
Enforced in code
before tool_call "issue_refund":
    if not caller.has_scope("refunds:issue"):
        return deny("not permitted")
    if call.amount > 50:
        return ask("duty_supervisor")
    return allow()
Runs in the application or the service, before the call executes, using the agent's configured identity. The model can propose the refund as often as it likes; the check decides, and every decision is logged. It holds as long as the code and its configuration are right, which is why it is tested and reviewed. In Claude Code, for example, a PreToolUse hook can return allow, deny or ask; a logging hook on the same event would enforce nothing.
When money or access is on the line, enforce it in code at the boundary, and test that code. Watch a refund get denied before execution.
This is gate 05 of the eight gates: every action typed, validated, and reversible, with the rules that matter enforced outside the model.
Questions people ask me
Short answers, in order of how often I hear them. Each one links back to the idea on the map if you want to go deeper.
Out of the box it is an assistant: a model with a conversation and standing instructions. It becomes agent-like when it is given tools (browsing, code, files) and allowed to decide when to use them. The product you are using may be either, depending on what is switched on. The test is: does it choose its own next step and act on it? The four kinds.
AI is the whole field. A large language model is one kind of AI: a program that writes by predicting the next word, very well. Spam filters, route planners, and image recognisers are AI too, and most of them are not language models.
Because it is built to produce the most likely next words, not to check them. When it lacks the fact, the most likely words still come out fluently. This is called hallucination. The fix is retrieval (letting it look the fact up in documents you trust), citations, and an evaluation that measures how often it happens.
Because a model has no memory of its own. It sees only what is in front of it for this request, called the context window. Products that "remember" are storing notes outside the model and placing them back into the context each time. That is memory as a feature of the system, not of the model.
The small chunks of text a model reads and writes, often parts of words. Everything about a model is counted in tokens: the price, the speed, and how much it can hold at once.
The standing instructions a model is given before the conversation starts: who it is, what it may do, how to answer. It is strong guidance, not enforcement. Anything that must never happen needs a rule in code, not a sentence in the prompt. The enforcement question.
Retrieval-augmented generation: before the model answers, the system searches your documents for the relevant passages and places them in front of it. An open-book exam instead of answering from memory. It is how you get an assistant to answer from your handbook rather than from the internet in general.
Usually not first. Fine-tuning changes how a model behaves and sounds; it is unreliable at adding facts, and it has to be redone when the facts change. For facts, use retrieval. Fine-tune when you need a consistent style or format, or a small model to do one narrow job cheaply.
Model Context Protocol, an open standard for connecting tools and data sources to AI models. Think of it as one connector shape: a tool built once as an MCP server works with any model or agent that speaks the protocol. It sits in the tools layer, between the agent and your systems. It standardises how the connection is made, not who is allowed to use it; permissions are still yours to enforce. The stack.
Function calling is how a model asks for a tool to be run: it emits a structured request that matches a schema you declared. MCP is how tools are packaged and discovered so that any model can find and call them. Function calling is the verb; MCP is the plug.
Several agents with different jobs, usually one coordinating the rest. You need it when one agent would have to hold too many tools or too much context to stay reliable. Most teams don't need it on day one. Hub and spoke.
It can tell you what decision it makes and who owns it. It runs as the user, with the user's permissions. Every action is typed, validated, and reversible where it matters. There is a test set that runs on every change, a trace that explains each run, a cost ceiling, and an off switch someone has tested. If any of those is missing, keep a person in the loop. That list is the eight gates, and you can run the check on your own system.
Where next
This page is the vocabulary. The SHAMS Method is how I decide where AI belongs in an estate and what has to be true before it acts. The playbooks are the build, tool by tool, in order.