Get in touch
Open to principal-scope roles · Phoenix, Arizona · Remote or hybrid
Open to principal-scope roles · Phoenix, Arizona · Remote or hybrid
The SHAMS Method · for principal-level architecture
A reference I built from fifteen years of enterprise architecture and the last stretch shipping agentic systems. It answers the three questions every leadership team is asking in the same meeting: what do we actually have, where would AI pay off first, and what has to be true before we let it act. Pick your industry, explore the map, run the gate check, keep the page.
S · Scope, in my words
Before any diagram, I sit with the people who own the outcome until they say what they are actually worried about. That conversation is the scope. Then I write the decision the system makes, who owns it when it's wrong, and what wrong costs, on one page, and get it signed. Scope an executive hasn't signed isn't scope; it's a hope, and it will be renegotiated the first time the pilot surprises someone.
The questions I ask
Layers of the estate it governs
On an agent, it governs
Ideas on the AI map
Signed off at
Built in detail in
Where I got this wrong once
I once let a pilot start without a definition of done. Six months in it still had users, a Teams channel and a renewed budget, and no decision. Now the exit criteria go in the first document, before the architecture, and the range goes in writing rather than the number the room wanted to hear.
H · Harden, in my words
I draw the boundaries before anything is allowed to act: which agent owns what and where control passes; who the system runs as, and what that identity may see; what each tool may do, and whether it can be undone. The platform enforces all of it. The prompt gets to ask nicely. This is where every cloud security topic on the site lives, because an agent is an identity doing things, and it should be watched and limited like one.
The questions I ask
Layers of the estate it governs
On an agent, it governs
Ideas on the AI map
Signed off at
Built in detail in
Where I got this wrong once
The most common enterprise AI failure I have reviewed is not a hallucination. It is an assistant returning data a user was never cleared for, through a service principal that was given Contributor during the pilot and never revisited. I have been the person who approved that service principal 'just for the demo'. It is never just for the demo.
A · Anchor, in my words
Every fact the system states comes from a source somebody owns, and the answer can say which one. Facts are retrieved at the moment they are needed, with permissions checked at query time; the agent never keeps its own copy. This is where the data platform work lives: the lakehouse, the semantic models, the lineage. If the data underneath is not governed, the agent is fluent and wrong, and no amount of prompt engineering fixes that.
The questions I ask
Layers of the estate it governs
On an agent, it governs
Ideas on the AI map
Signed off at
Built in detail in
Where I got this wrong once
Early in my career I shipped dashboards that got applause and then became the most expensive thing in the system, because the foundation underneath was still catching up to what the front end had promised. The AI version of the same mistake is an index built once from a demo folder. Both look perfect on launch day. Both drift. Now the data contract comes first, and the index refresh is tied to the source.
M · Measure, in my words
Before anything ships I want two numbers that move: one for quality and one for money. The quality number comes from a fixed case set that includes the ugly inputs, run on every change to a prompt, a tool, or a model. The money number is cost per run, measured from week one, with a ceiling. Without these, every improvement is an anecdote and every budget is a surprise.
The questions I ask
Layers of the estate it governs
On an agent, it governs
Ideas on the AI map
Signed off at
Built in detail in
Where I got this wrong once
On my own AWS platform I first set the cost alarm where it would only catch disasters. Then I set it low enough to be occasionally annoying, and it has paid for itself three times: a retry loop over a weekend, a storage class with retrieval charges I had not read carefully, a test environment I forgot existed. Cost is the fastest signal you have. Set the alarm at 'surprising', not 'catastrophic'.
S · Sustain, in my words
A system is not finished when it works. It is finished when someone can stop it in under a minute, explain any run six months later, change the prompt or the model without fear, and say when the pilot ends. This is where the platform foundations and operations topics live: landing zones, policy as code, traces, cost attribution, runbooks. Boring is a feature here. Predictable beats clever.
The questions I ask
Layers of the estate it governs
On an agent, it governs
Ideas on the AI map
Signed off at
Built in detail in
Where I got this wrong once
I have seen the invoice that 'send everything to Sentinel' produces: every verbose log flowing in, priced per gigabyte, and a SOC drowning in data it never wrote a detection for. Seeing everything felt safe. It was expensive noise. Now it is detection first, ingestion second, and the same rule applies to agent traces: record what you will need to answer 'why did it do that', and no more.
I have never watched an AI project fail at the model. They fail at the gate nobody opened.
Five moves, in order. Everything on this site hangs off them: every layer of the estate, every idea on the AI map, every playbook, every gate. Open a move to see what it governs, the questions I ask, and where I learned it the hard way.
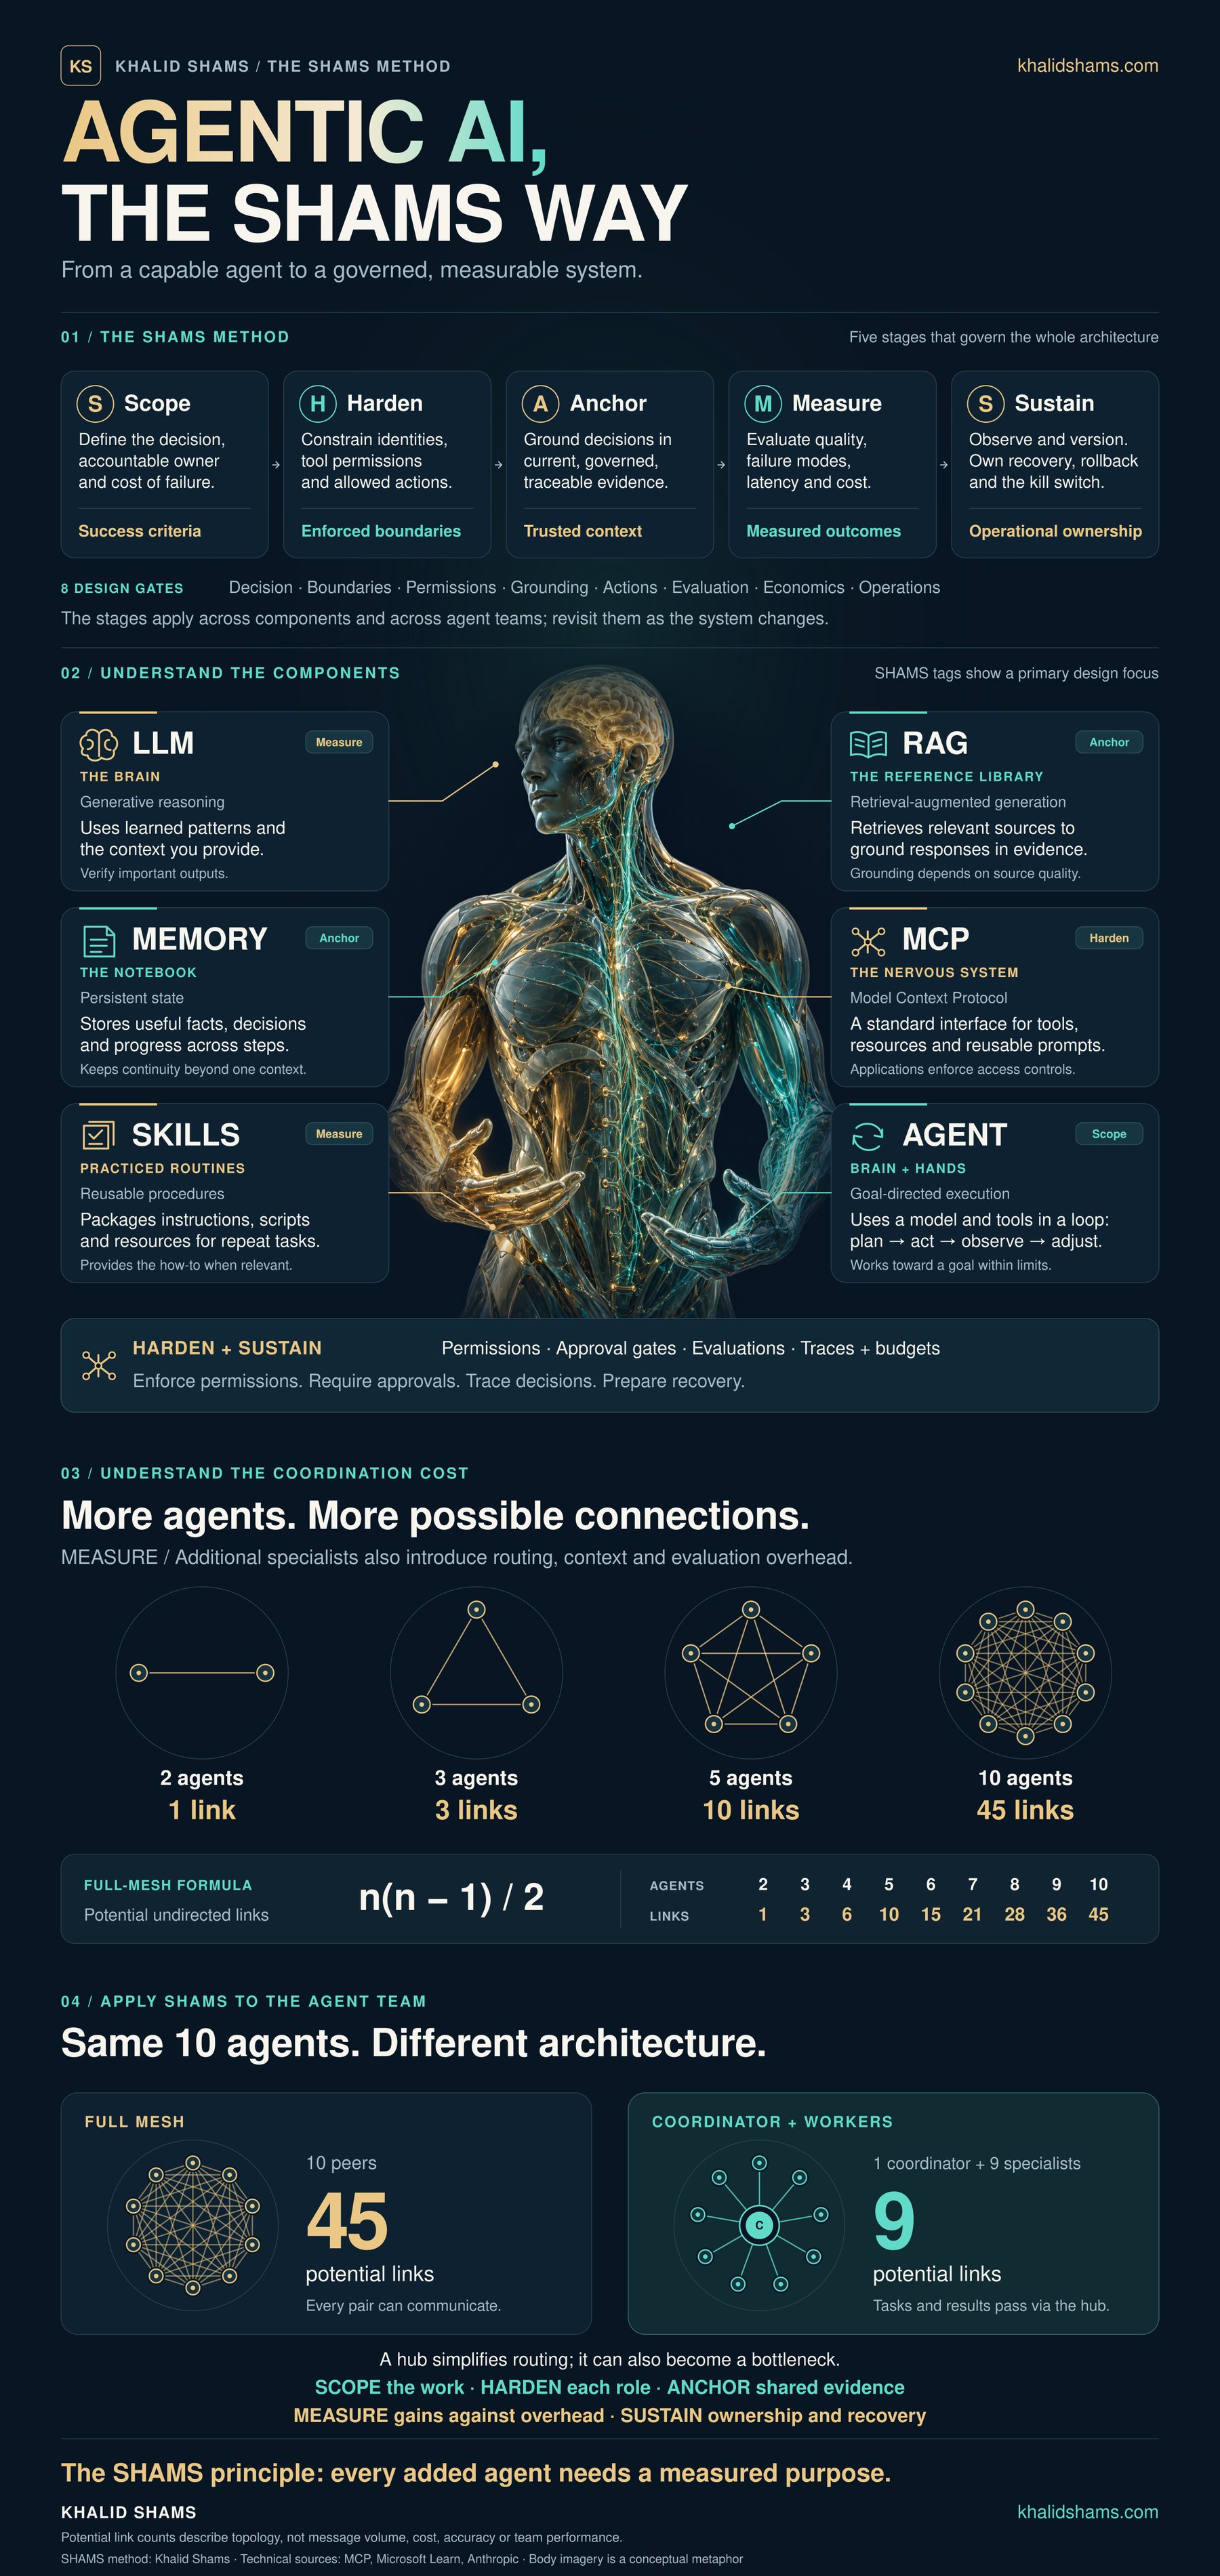
Agentic AI, the SHAMS way
The five moves above govern the whole estate. Here they are applied to the thing every team is building right now: an agent. Six components, each tagged with the stage that governs it first, then the arithmetic that decides how many agents you actually need. Pick a component, or pick a stage and watch what it governs light up.
Follow one request through all of these in the SHAMS AI Atlas: the same components working together on a damaged-order case, with the SHAMS lenses as overlays and what changes when a permission is denied.
A delivery field guide
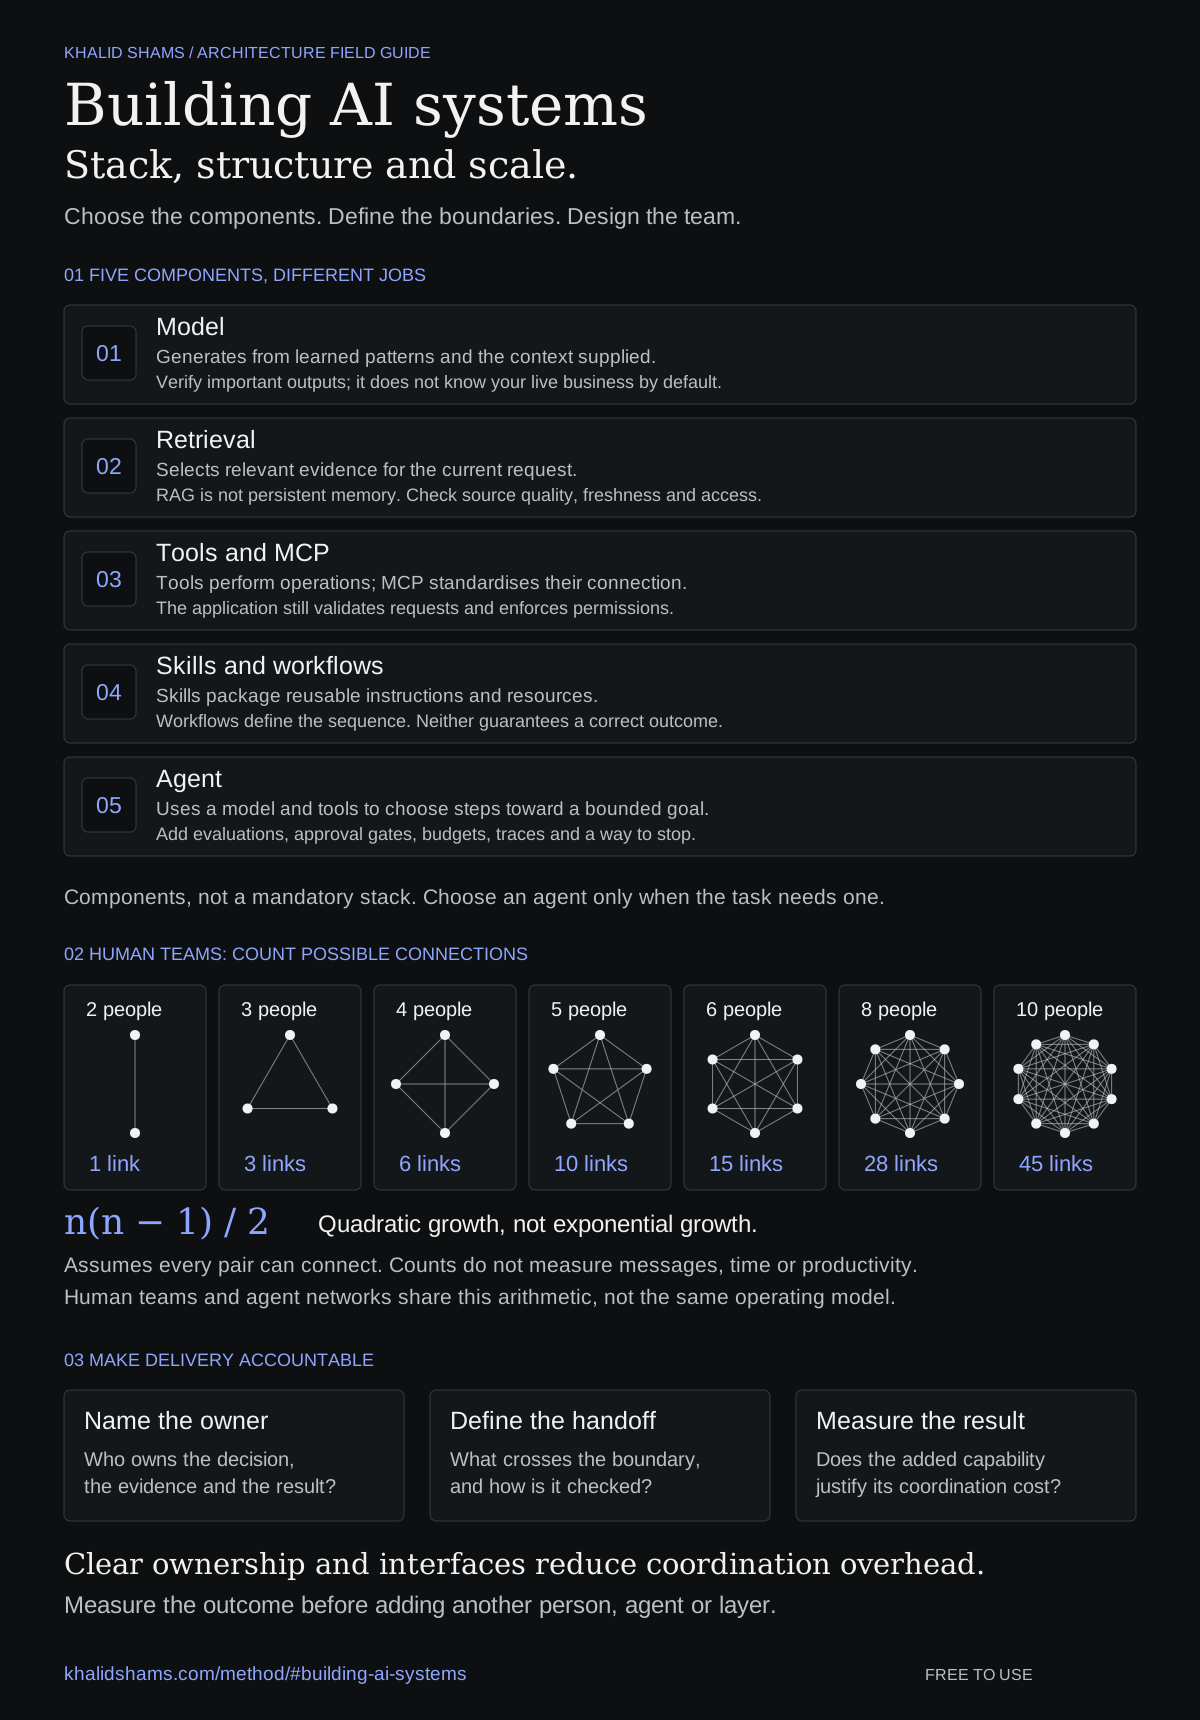
I start with the work, then choose the components and the people responsible for them. A useful model is one part of the system. Clear evidence, controlled actions and explicit handoffs turn it into something I can operate.
These are five connected components, not a mandatory build sequence. The seven-layer architecture explains where they sit. Retrieval and stored memory have different jobs; an agent is only needed when the next step must be chosen dynamically.
Generates from learned patterns and the context supplied.
Verify important outputs; it does not know your live business by default.
Inspect model →Selects relevant evidence for the current request.
RAG is not persistent memory. Check source quality, freshness and access.
Inspect retrieval →Tools perform operations; MCP standardises their connection.
The application still validates requests and enforces permissions.
Inspect tools and mcp →Skills package reusable instructions and resources.
Workflows define the sequence. Neither guarantees a correct outcome.
Inspect skills and workflows →Uses a model and tools to choose steps toward a bounded goal.
Add evaluations, approval gates, budgets, traces and a way to stop.
Inspect agent →A scalable, text-selectable poster for design reviews. Download light SVG · Download dark SVG
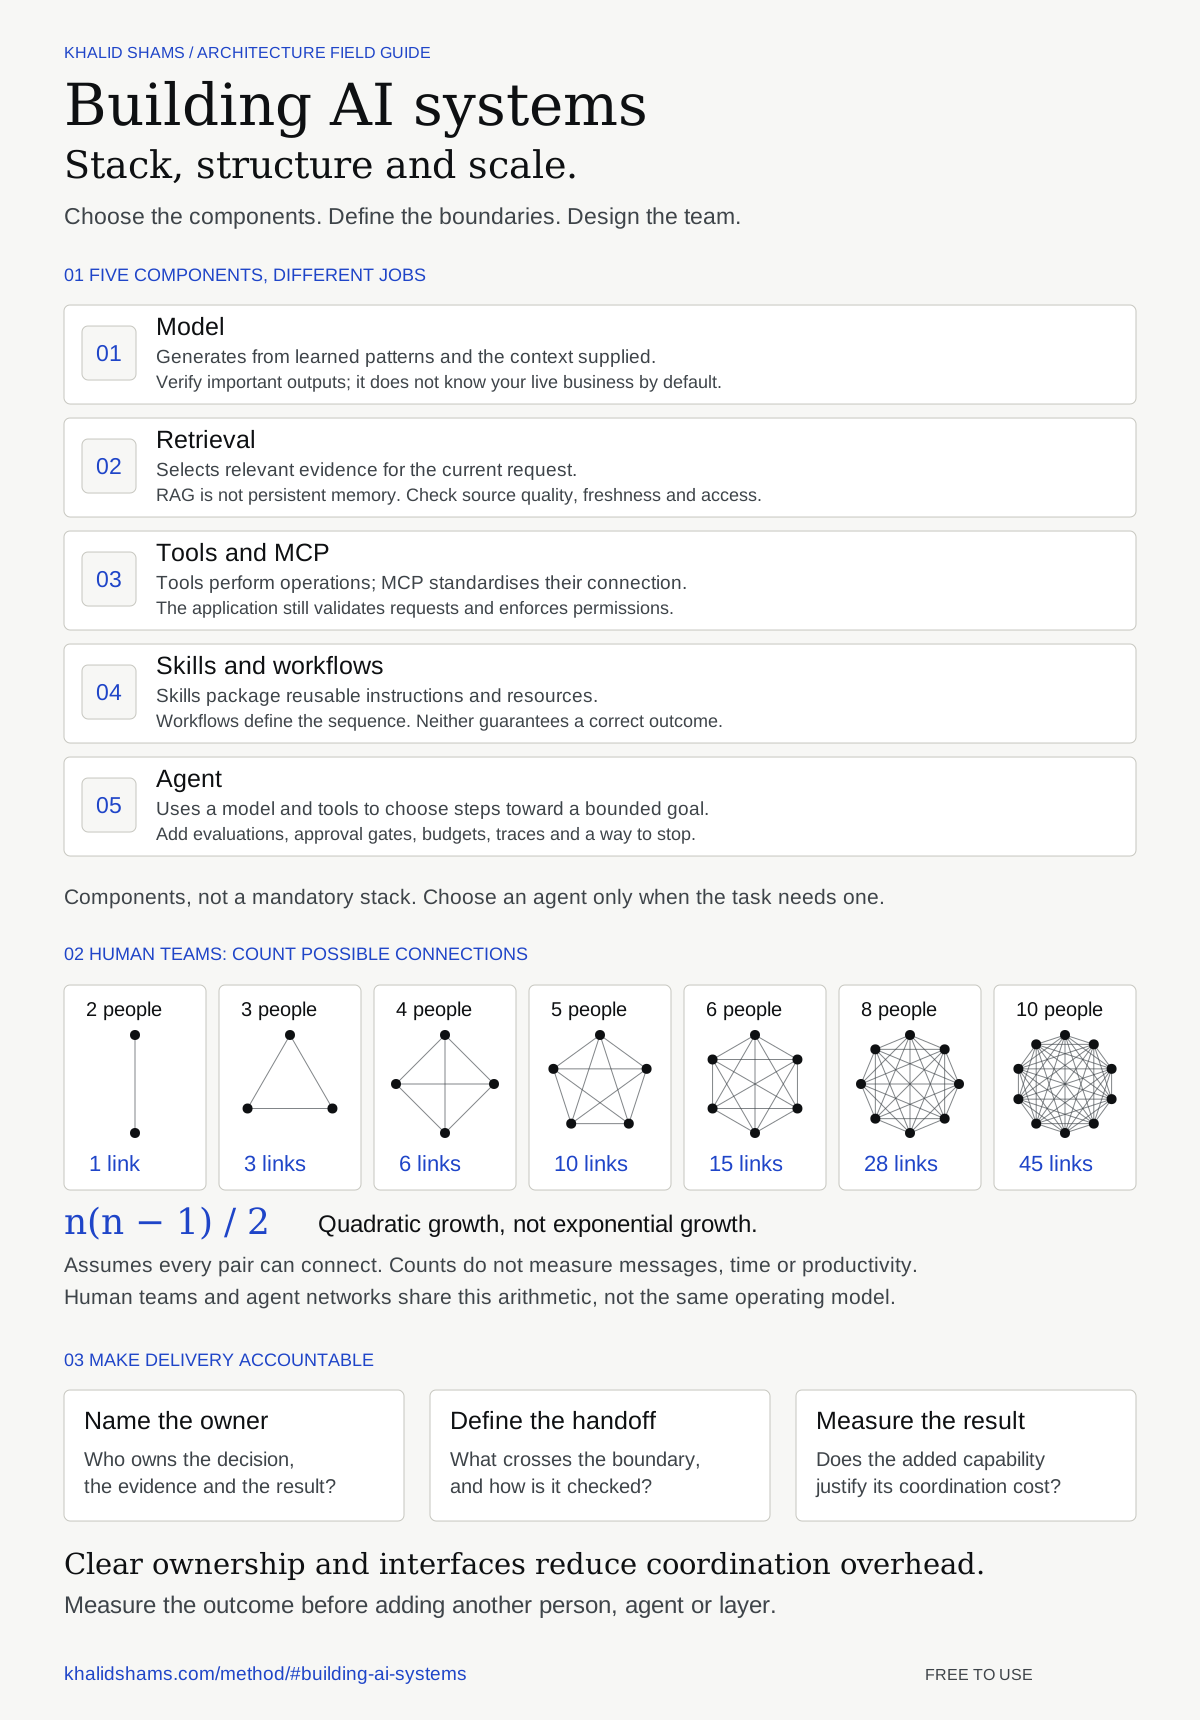
Technical references: MCP architecture · Retrieval-augmented generation · Agent skills
Agent · brain + hands · Scope
Uses a model and tools in a loop: plan, act, observe, adjust. Works toward a goal within limits.
The agent is the part that decides, so it is the part that needs a scope first. Before I draw one, I write the decision it makes, who owns that decision when it's wrong, and what wrong costs. An agent without that page is a demo with a budget.
The question I ask
What decision does it make, who owns it when it's wrong, and what does wrong cost?
MCP · the nervous system · Harden
Model Context Protocol: a standard interface for tools, resources and reusable prompts.
MCP standardises how an agent reaches a tool. It does not decide whether it should. The application still enforces access per user, and every write still has to be typed, validated and reversible. A clean protocol makes it easy to connect everything, which is exactly why the boundary has to be drawn on purpose.
The question I ask
What is the agent allowed to see and do, per user, enforced by the platform?
RAG · the reference library · Anchor
Retrieval-augmented generation: retrieves relevant sources to ground responses in evidence.
Grounding is only as good as the source. If the index holds last year's policy, the agent will quote it with confidence. Retrieval earns its place when every passage carries where it came from, who owns it, and when it was last true.
The question I ask
Where does every fact come from, and is that source governed?
Memory · the notebook · Anchor
Persistent state: stores useful facts, decisions and progress across steps, beyond one context window.
Memory keeps the work continuous: what was decided, what was tried, where it got to. It can also hold facts, preferences and summaries, but it is not the system of record, and it only helps when the application loads a relevant, permitted, fresh entry. Business facts that change, like a balance or an order status, are better read from the source when they matter. Mixing the two is how an agent ends up repeating something that stopped being true.
The question I ask
What is it allowed to keep, for how long, and who can read it back?
LLM · the brain · Measure
Generative reasoning: uses learned patterns and the context you provide.
The model is the one component I don't control, so it is the one I measure hardest: a harness of real cases, a number that moves when quality moves, and a cost per run. When the model version changes, the harness runs before anyone ships.
The question I ask
Can you show me the harness, and what number moves when quality moves?
Skills · practiced routines · Measure
Reusable procedures: instructions, scripts and resources for repeat tasks, loaded when they're relevant.
A skill is a routine, and routines can be tested like routines: same input, expected output, every time the model or the source underneath changes. A skill is still guidance, not enforcement, and it cannot grant a permission the runtime has not. Anything that touches money, compliance or access needs a check in code at the boundary: a blocking hook, middleware, or the service's own authorization.
The question I ask
Does the routine still pass when the model or the data underneath it changes?
Across all six · Harden + Sustain
Permissions, approval gates, evaluations, traces and budgets.
No single component owns recovery. It sits across all six: an off switch someone has actually tested, traces that explain why it did what it did, versioned prompts and models, and a budget that stops the run before the invoice does.
The question I ask
Can you stop it, explain it, and change it safely?
The stage on each component is its primary design focus, not its only one. Every component passes all five moves; this is where I start.
More agents, more possible connections. Every specialist you add also adds routing, context and evaluation overhead. Move the slider.
Full mesh
5 peers. Every pair can talk to every other pair.
Coordinator + workers
1 coordinator + 4 specialists. Tasks and results pass through the hub.
Full-mesh formula
n(n − 1) / 2
grows with the square. A coordinator grows in a line: n − 1.
A hub simplifies routing; it can also become a bottleneck, and its context fills first. Potential link counts describe topology, not message volume, cost, accuracy or team performance.
People and delivery
I use this count to ask where a handoff needs an owner or a clearer interface. It assumes every pair of people can connect. Real teams organise around roles, shared artefacts and boundaries; they do not use every possible connection equally.
6 people · 15 possible pairwise connections
n(n − 1) / 2 grows quadratically, not exponentially. This is a topology count, not a prediction of messages, meetings, delivery time or productivity.
Fewer links do not prove a better team. A coordinator can reduce direct connections while creating a bottleneck. For people, inspect decision rights and handoffs. For software agents, also inspect permissions, context isolation, retries and evaluations.
Who owns the decision, the evidence and the result?
What crosses the boundary, and how is it checked?
Does the added capability justify its coordination cost?
Clear ownership and interfaces reduce coordination overhead. I measure the outcome before adding another person, agent or layer.
Same 5 agents. Different architecture. Before the next one is added:
Every added agent needs a measured purpose.
Keep it
The one-page version of this section, for a slide, a design review, or the wall. Download the one-pager · A coordinator and specialist, step by step · How hub and spoke works · The agentic AI playbook
The map
Two domains: the infrastructure the estate needs, and the AI uses it can support. Owners still need to be named in a review. Solid lines are declared dependencies, not observed traffic. Choose an industry to re-weight payoff and risk. Select a node, then inspect one dependency and its potential impact. Drag a node to rearrange the drawing.
The autonomy ladder
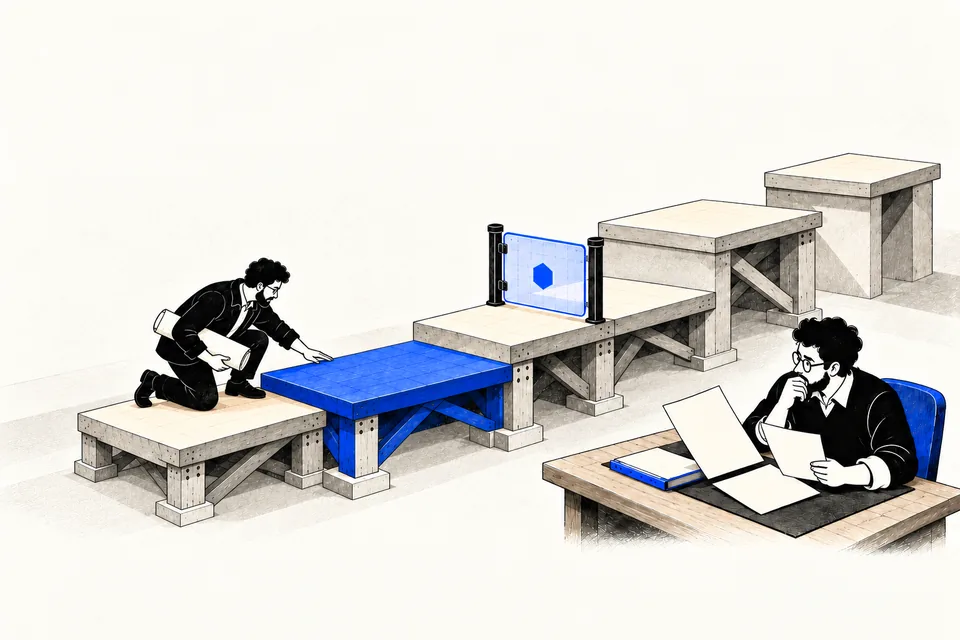
Most organisations should climb this one rung at a time, per use case, with the safeguards for the next rung in place before stepping onto it. The rung tells you which gates matter most.
People do the work; AI is absent or used ad hoc on personal accounts. Risk: shadow AI with company data in it.
Needs: an acceptable-use policy and a sanctioned tool, nothing more.AI drafts, summarises, searches. A person reads everything before it goes anywhere. Low blast radius, immediate value.
Needs: identity (gate 03) and grounding (gate 04). The place to start.AI proposes a decision with evidence; a person approves inside a designed queue. Extraction, triage, classification live here.
Needs: boundaries and a real review queue (gate 02), a harness (gate 06).AI acts without per-item review inside narrow, reversible bounds. Someone watches the aggregate, not each case.
Needs: typed, idempotent, reversible actions (gate 05), cost ceilings (gate 07), an off switch and traces (gate 08).Multi-step agents plan and act across systems with a human only at consequence points. Rare in regulated industries today, and it should be.
Needs: every gate closed and signed, re-opened whenever a tool, source, or model changes.The eight gates
Each gate is a question the system has to answer in writing before it is allowed to act: who owns the decision, what each agent may see and do, where every fact comes from, whether every action is typed and reversible, how quality and cost are measured, and how it can be stopped. Pass them in order. The first open gate is the one to fix.
Gates 1 to 4 are answered before a line of orchestration code exists. They take about a week and they decide most of the architecture.
Every gate produces one page. Question, answer, evidence, owner, date. If it won't fit on a page, the thinking isn't done.
A gate isn't passed because the architect says so. The person accountable for that gate signs it, and a gate can be reopened when something changes.
Gate 01 · Decision
Vague scope is how an agent does the wrong thing confidently. "It helps users with X" is not a decision. A system that decides which invoice to pay is a different build from one that drafts the email asking about it, and nobody can design the controls until that line is drawn. The owner question is the one that stalls projects: if the answer is a committee, the project isn't ready.
In the clinical platform I architected, the system never decides a diagnosis. It decides which document goes to which human queue, and how urgently. Writing that sentence down shaped everything that followed.
Gate 02 · Boundaries
Handoffs are where failures hide. One "do everything" agent can't be tested, priced, or explained. A pipeline of narrow specialists with a planner on top can be swapped piece by piece. And a human in the loop is only a control if the loop was designed: if the review screen is bad, the human stops reviewing and starts approving.
On the system I delivered on Anthropic's Claude platform, the planner decomposes the task and specialists retrieve, analyse, and act, each with a bounded scope and an explicit handoff. The planner is where the care goes.
Gate 03 · Permissions
The most common enterprise AI failure I've seen isn't a hallucination. It's a service principal with broad access wired in during the pilot, and an assistant that cheerfully returns data the user was never cleared for. Policy in the prompt is a suggestion. Policy in the platform is a control.
Governance isn't the brake. On the security and data strategy work I contributed to, controls landed before workloads, so the AI features inherited governance instead of fighting it.
Gate 04 · Grounding
If the data underneath isn't governed, the agent is fluent and wrong. Retrieval systems rarely fail loudly; they drift. Stale indexes, permissions that changed after indexing, chunks that lost their context, citations to documents that no longer exist. And the moment an agent keeps its own copy of a fact, you have a second source of truth that nobody governs.
Moving an estate onto Microsoft Fabric with real medallion layering changed the question from "where is the data" to "who owns this layer." That ownership is what made grounding an agent on it safe.
Gate 05 · Actions
An agent will retry. That isn't a bug, it's how they work. If a tool sends an email, creates a ticket, or moves money, and the first call succeeded, you now have two. A tool call is an API call and deserves the same discipline as any other integration, and in most prototypes it gets none.
In the clinical system, name matching proposes and never merges. A human confirms that two records are one person, and that decision is logged with who made it. The source document stays immutable, forever.
Gate 06 · Evaluation
Every change to an agentic system, whether a prompt, a tool, a model version, or a retrieval tweak, has an unknown blast radius. Without a regression suite you aren't iterating. You're gambling and calling it iteration. If the answer to "show me the harness" is a pause, you're looking at a prototype wearing production clothes.
The Claude platform build shipped with an evaluation harness and a written failure-mode catalogue as deliverables, not afterthoughts. That's what let production hardening happen in weeks instead of quarters.
Gate 07 · Economics
A license costs the same whether people use it or not. An agent costs more the better it works, sometimes faster than linearly, because successful agents get asked harder questions and take more steps to answer them. Cost per run is an architecture decision, not a finance surprise.
On the platform I run alone on AWS, the cost alarm is set lower than I think I need. It has paid for itself three times. The same rule scales to an enterprise estate.
Gate 08 · Operations
Agents fail in ways that are fast, repetitive, and confident. By the time a human notices, the agent has done the wrong thing forty times. Logs tell you what it did; only a trace tells you why. And a model version change is a production deploy, whether or not the team treats it as one.
Every pilot I scope now has its exit criteria in the first document: the numbers that trigger a production build, the numbers that trigger shutting it down, and a date. Both outcomes are wins. The only losing outcome is drifting into permanence.
The gate check
This is the same check I run in the first week of an engagement. Nothing you tick leaves this page. Tick what's true today, not what's planned.
Work through the gates in order. The first open gate is the one to fix first.
The record
Every gate ends in the same short record. It's deliberately plain so that it gets written, and so an auditor, a new engineer, or a future version of the team can read it in a minute.
GATE          03 · Permissions
QUESTION      What is the agent allowed to see and do, per user, enforced by the platform?
ANSWER        The agent runs as the signed-in user via on-behalf-of flow. It reaches the
              gold layer of the claims lakehouse and the ticketing API, nothing else.
              The service identity can only write traces and read configuration.
EVIDENCE      Identity diagram v3 · RBAC assignments export · access log sample from a
              test user with restricted scope returning a correct denial
OPEN ITEMS    PIM activation for the two privileged tools (owner: platform team, due 14 Nov)
OWNER         Head of Security Engineering
SIGNED        12 Nov 2026
REVISIT       When a tool is added, when a data source is added, or at 90 days
Why gates and not a checklist
A checklist lets you do the exciting part first and tick the boundaries later. By then the exceptions are already in production and every control is a negotiation with something people depend on. Gates force the sequence: decide, bound, permit, ground, and only then build. It looks slower on the plan. It is the only version that stays fast. The writing is where each gate gets argued about in public, twice a week.